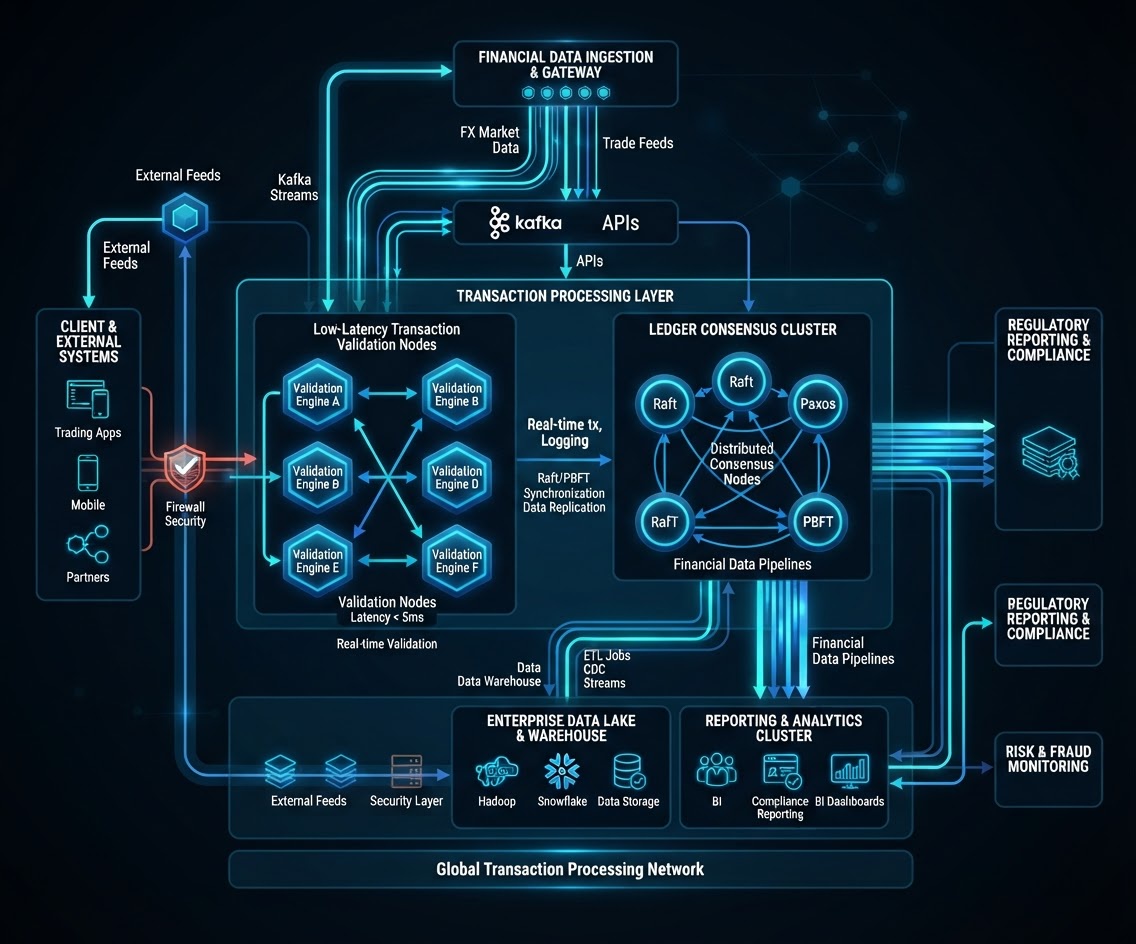
Plexus Dynamics modernizes core infrastructure, eradicates technical debt, and empowers mission-critical enterprises with fault-tolerant cloud environments and real-time operational intelligence.
Zero Trust Core
Automated Governance
We architect, modernize, and reinforce core enterprise stacks. Each offering is executed with deterministic modeling, rigorous automation, and mathematical precision.
Construct high-fidelity mathematical digital twins and stochastic feedback models that simulate distributed traffic anomalies, systemic latency cascades, and resource utilization before deployment.
Eliminate operational silos through asynchronous message backbones, legacy system adapter layers, and bidirectional event meshes that maintain strict transactional consistency across fragmented vendors.
Implement auditable, enterprise-grade AI pipelines. We fuse fine-tuned local LLMs, deterministic tool-calling agents, and real-time retrieval-augmented generation (RAG) within strict governance boundaries.
Multi-region active-active deployments constructed with immutable Infrastructure as Code (IaC). Designed for zero-RPO/zero-RTO disaster recovery and automated automated blue-green delivery.
Our senior systems architects review your latency profiles, service meshes, and failover topologies with zero vendor lock-in bias.
Simulate real-time traffic surges, inject node failures, and observe how our self-healing topology dynamically redirects requests with zero packet drop.
When a catastrophic link severance occurs, our mesh rebalances ingress at the DNS and eBPF layers within milliseconds, bypassing failed points before customers perceive downtime.
Explore how Fortune 500 enterprises and hyper-growth operators partner with Plexus Dynamics to eliminate systemic downtime, compress latency profiles, and automate governance.
The clientβs legacy COBOL settlement core suffered from severe throughput locks during market volatility spikes, with settlement lag exceeding 140ms. Plexus Dynamics engineered a zero-downtime micro-partitioned event mesh that runs active-active across 3 availability regions.
HIPAA-governed clinical query execution was failing under multi-terabyte genomic sequencing loads. Plexus Dynamics deployed secure multi-party enclave computing with dynamic caching layers, compressing runtimes from 8 hours to under 35 minutes.
Severe cold-chain sensor outages caused repeated perishable inventory spoilages during cloud region network partitions. We instituted decentralized edge hubs capable of autonomous local consensus and seamless cloud reconciliation.
Peer-reviewed engineering briefs, distributed consensus benchmarks, and practical implementation blueprints written directly by our staff infrastructure engineers.
Empirical stress-testing of 350 enterprise topologies across AWS, GCP, and bare-metal nodes. Analyzes mean time to reroute (MTTR), split-brain risks, and edge BGP behavior during cross-oceanic fiber cuts.
A architectural standard for running autonomous LLM agents in regulated environments. Introduces formal verification gates, atomic state rollbacks, and sandboxed tool-execution protocols.
Detailed walkthrough of dynamic CPU/memory overcommitment, cold-tier object compaction, and spot-fleet fallback mechanisms that systematically trim 40%β65% off enterprise public cloud bills.
No promotional marketing spam. Exclusively technical post-mortems, whitepaper pre-prints, and infrastructure benchmarks curated for senior engineering leaders.
Engage directly with our Principal Systems Architects. No generic sales pitchesβstrictly peer-to-peer technical discovery, topology evaluations, and concrete failover risk assessments.
Your consultation is held directly with a Senior Distributed Systems Architect with extensive production experience in high-throughput enterprise infrastructure.
We execute mutual non-disclosure agreements prior to the session. Share system topology schematics, latency profiles, and pain points in full legal confidence.
Following the 45-minute working call, our team delivers a succinct executive memo outlining detected single points of failure, bottleneck remediations, and estimated ROI.
A staff architect has been assigned to your profile. The mutual NDA and calendar invitation link have been dispatched to your corporate inbox.
Real-time access to your dedicated deployment portals, live platform telemetry, technical documentation, and 24/7 Tier-1 engineering response channels.
Track architecture delivery milestones, sprint pipelines, multi-region CI/CD builds, and cluster provisioning telemetry in real time.
Explore OpenAPI 3.1 specifications, Rust/Go SDK reference libraries, Terraform module registries, and custom Raft consensus guides.
Bypass ticketing tiers with a dedicated, encrypted Slack or Microsoft Teams channel linked directly to your designated staff infrastructure lead.
Direct pager bridge connecting instantly to our on-call Site Reliability Engineering commanders for unannounced catastrophic cloud partitions.